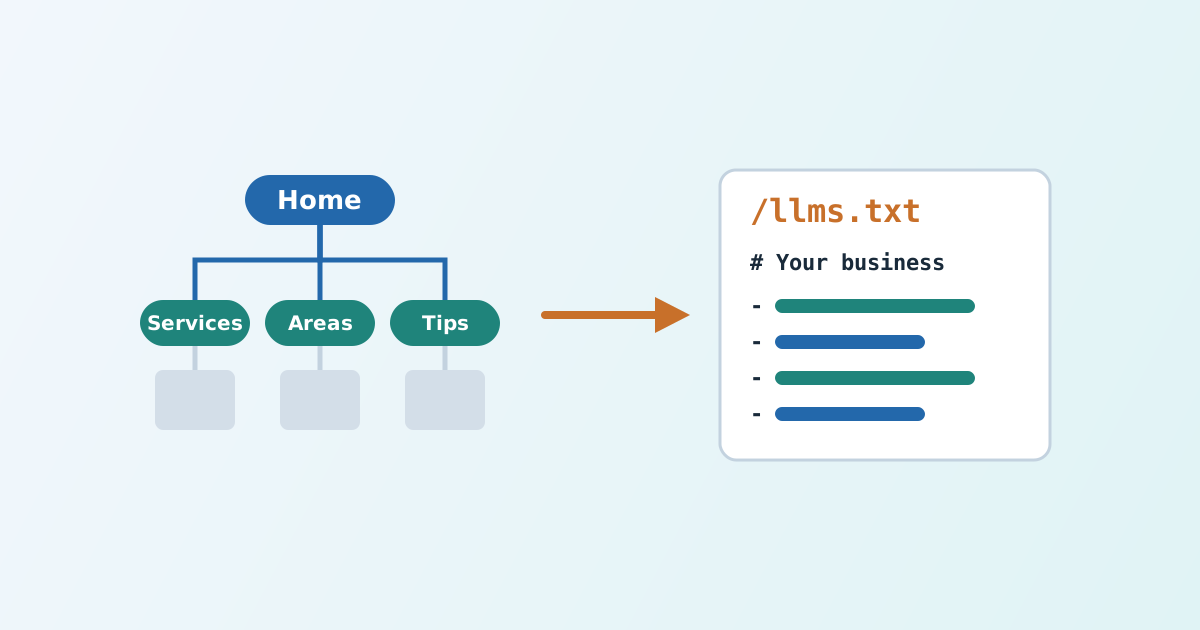
An llms.txt file is a plain text page at the root of your site, at
/llms.txt, that tells AI tools what your business is and which pages
matter, with a line about each. It is cheap, it is new, and it is oversold.
Some providers pitch it as the way into ChatGPT’s answers. Nothing we have
seen supports that, and Google does not use the file. We add one anyway,
because on a site we build it is generated from the pages themselves and
costs nothing to keep current. Here is what it is, who reads it, what ours
looks like, and what to expect from it, which today is not much.
What llms.txt is#
A proposal from September 2024 by Jeremy Howard of Answer.AI, written as a
plain Markdown file: the site’s name as a heading, a one-paragraph summary,
then lists of links grouped under headings, each with a short note. It is not
robots.txt. It does not allow or block anything. It is a summary for a
machine that has already decided to read you, so it can find the pages worth
reading without wading through menus, scripts, and footers.
Who reads it, and who does not#
As of 2026, Google ignores it, and few of the crawlers that feed AI answers fetch it. Where it does get used is closer to the ground: AI coding tools and assistants that a person points at a site and asks to read. Many software documentation sites publish one for exactly that reason. So treat it as a small, cheap bet that costs nothing to place, not as a channel. The work that actually changes what AI assistants say about a local business is listings that agree, real reviews, and pages worth quoting, which is our AI search optimization service.
An example from this site#
Part of our own file, just below its title and one-line summary. You can read all of it at /llms.txt:
## Site
- **Home**: https://frazemarketing.com/
- **Focus**: Websites and local search for North Texas businesses
- **Request a Quote**: https://frazemarketing.com/contact/

## Other Areas We Serve
- [Marketing for Allen, Texas Businesses](https://frazemarketing.com/service-areas/allen/): ...
Under each heading, every line is a page: its title, its address, and the same one-line description a search result shows. A tool that reads this knows in a few hundred words what we do, where, and where to read more.
What this service covers#
On a site we build, the file is generated every time the site is published, from the pages themselves. A new page with a proper title and description appears in it on the next publish, and a removed page drops out. Nobody edits it by hand, so it cannot go stale or disagree with the site. It draws on the same record of your facts as your JSON-LD, so the two say the same thing.
For a site someone else built, we start from what your site already publishes and write a file that matches it, with the pages grouped the way a customer would look for them.
How pricing works#
It is part of every site we build. For a site someone else built, it goes into the same monthly arrangement as the rest of our work, usually alongside the JSON-LD and AI search work it belongs with, and the figure comes in writing after the first call.
“Will llms.txt get us into ChatGPT?”#
Nobody can promise that, and this file is the weakest lever there is for it. What moves how AI assistants describe you is the same evidence everything else rests on. We re-ask the assistants the same questions every month and show you the answers, so you can see for yourself what is changing.